I had a simple idea for an experiment: can discrete video rollouts from a VQ-VAE + Transformer pipeline be mapped back into a smoother continuous latent space with latent diffusion to improve coherence and visual fidelity?
I show that they can. A framewise VQ-VAE and GPT2 model dynamics in a coarse discrete latent space, and a latent-diffusion U-Net conditioned on those rollouts recovers AE latents with substantially better smoothness and visual fidelity than direct VQ decode alone.
I thought it was really exciting to bridge tokenized video rollouts into coherent continuous latents.
Overview
In my head, the project eventually settled into a simple modular design: (1) train a hierarchical framewise VQ-VAE to produce a discrete token representation of video, with the reconstruction objective treated as a means to learn a usable tokenization rather than the final visual target; (2) train GPT2 over those tokens as a lightweight rollout model; (3) train a latent-diffusion U-Net to map VQ token grids into a separate autoencoder latent space; and (4) train that autoencoder to provide a cleaner reconstruction target for the diffusion model.
This was the basic plan: first train a VQ-VAE to learn a compact frame representation, then train a 90M-parameter GPT2 to predict future frame tokens from the discrete VQ bottleneck.
Unlike VideoGPT, I did not want the VQ-VAE to carry the entire burden of final reconstruction quality. The goal was to let the discrete model handle coarse video structure and rollout, then add a second path for recovering cleaner frames. To do that, I trained a separate reconstruction autoencoder, and then trained a latent-diffusion model conditioned on VQ token grids to recover that autoencoder’s latent space. This lets the GPT2 rollouts remain useful even when the direct VQ decode is visibly coarse.
Vector-Quantized Variational Autoencoder
The VQ-VAE compresses each frame into a discrete latent representation. Unlike a standard VAE, which maps into a continuous Gaussian latent, the encoder output is snapped to entries in a learned codebook. For this project that was useful for a simple reason: discrete spatial codes are easy to model with GPT-style autoregressive architectures.
Instead of optimizing purely for sharp pixel reconstruction, I trained the VQ-VAE with a multi-scale L1 loss together with the standard codebook and commitment losses. The goal here was not perfect frame recovery; it was to learn a stable tokenization that preserved enough structure for rollout modeling.
VQ-VAE:
Where for multiscale-L1:
And our VQ loss:
This is one of the main ways the project diverges from VideoGPT. I did not want the same model to be responsible for both discrete representation and final visual quality. I wanted the VQ side to remain a compact, usable state space for modeling, even if its direct reconstructions were imperfect.
The VQ-VAE itself went through a few iterations. At a high level, the design goal was consistency rather than sharpness: learn tokens that stay useful across nearby frames and preserve enough coarse structure for the autoregressive stage to work with. I trained it in stages, starting from a plain reconstruction-focused setup and later introducing perceptual pressure. In a project like this, the exact decoder details mattered less than whether the token grid ended up stable and informative enough to drive the later models.
The direct VQ-VAE decode is blurry, which is exactly why I split the system in the first place. The point here is not that the VQ decoder should win on visual fidelity; it is that the token grid still captures enough structure to be useful as a rollout space. In this version I only encode each frame independently in 2D, but a 3D spatiotemporal tokenizer would be a natural next step if the goal were to push more motion information into the representation itself and take some pressure off GPT2.
Reconstruction Autoencoder
The reconstruction autoencoder gives diffusion a cleaner target space later on. Architecturally it is fairly standard: stride-2 downsampling, residual blocks with GroupNorm + SiLU, and a mirrored decoder. The point was not to invent a new autoencoder, but to have a continuous latent space that was more reconstruction-friendly than the discrete VQ codes.
Similar to the VQ-VAE, I leaned on multi-scale reconstruction objectives, though here the emphasis was different: this model is explicitly meant to carry more visual detail. I treated it as a practical target space for the diffusion bridge rather than as a standalone claim about reconstruction quality.
The reconstruction AE is clearly better than the direct VQ decode, but it is still a compromise. For this demo I used a fairly small latent grid, which was enough to recover broad structure and some text, but not enough to preserve finer typography and texture. You can see that very clearly in the DAMART catalog example, where the larger layout is readable but the small text softens and blurs.
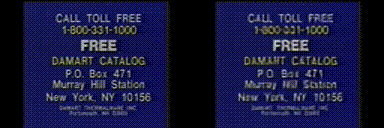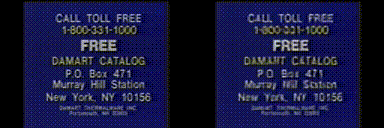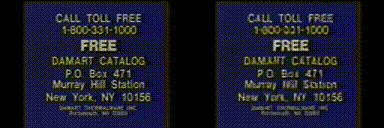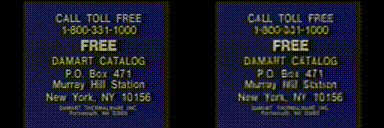
I could revisit this with a richer latent space, but for the purpose of this experiment it was good enough: clearly better than the VQ decode, and stable enough to use as a diffusion target.
GPT2
For the rollout model I used a mostly standard GPT2 backbone with a few modern conveniences: RMSNorm instead of LayerNorm, SwiGLU instead of a GELU MLP, scaled dot-product attention, explicit KV caching, frame embeddings, 2D spatial position encodings, and a separator token. The point was not to be novel here; it was to use a familiar autoregressive model on top of a discrete video representation.
The first seven frames of a clip are used as conditioning and GPT2 predicts the next eight. As expected, long rollouts diverge, but even partial success was enough to justify continuing, because the diffusion bridge only needs the predicted token grids to remain structurally useful for a short horizon.
This stage was also constrained by hardware. The practical questions were simple: what can I train on two 3090s, and what is the quickest path to rollout modeling over discrete frame representations? GPT2 was not chosen because it was the most elegant answer, but because it was a solid and very usable one.
The early tests were promising enough to keep going. Once the system starts rolling out beyond the conditioning window, though, inference becomes a design problem in its own right: how much ground truth should remain in the window, when should the model switch fully to autoregressive rollout, and how should one detect when the rollout is no longer trustworthy?
I kept the rollout logic simple and added motion-aware weighting across the predicted frames. Even in this stripped-down setup, the GPT2 stage was enough to make the larger experiment worth testing.
Latent Diffusion
The diffusion stage is the unusual part of the project. Rather than diffusing directly in a single latent space, I used diffusion as a bridge: condition on the VQ token grid, and recover a continuous AE latent that can be decoded into a cleaner frame.
In the naive version, this works badly. A token grid by itself is a weak and coarse conditioning signal, and directly asking diffusion to recover AE latents from that representation produces unstable results. The image below is what that first pass looked like.
It does something, but not enough. The main improvement was to introduce optional temporal conditioning. In practice that meant conditioning on the previous frame latent when available, occasionally corrupting or dropping that signal, and scheduling the temporal reliance so the model could first learn the basic mapping and later use more sequential information.
That made the bridge much more usable. The model effectively learns an association between VQ token structure and AE latent structure, with temporal conditioning acting as a stabilizer rather than a strict requirement. Keeping that conditioning optional is important, because at rollout time the future GPT2 token grids do not come with matching AE latents.
The recovered frames gain detail quickly, but they are still sensitive to abrupt motion and scene changes. There is also an unavoidable start-of-video weakness because the temporal setup always has to decide what to do at frame zero. When adjacent frames differ too sharply, the model tends to inject noise, which is exactly the kind of failure you would expect from a temporal conditioning scheme built around local frame pairs.
A practical way to handle this is to treat temporal conditioning as something to modulate at inference time. If two neighboring frames are too dissimilar, the previous-frame signal can be weakened, blended, or replaced with the same kind of fallback used when that conditioning is dropped during training. The visualizations here use that kind of inference-side adjustment.
Video Shim
The last step is to run diffusion on GPT2-generated rollouts rather than only on ground-truth token grids. Conceptually this is the whole point of the pipeline: let the discrete model generate coarse future structure, then let the diffusion bridge recover cleaner continuous latents from it.
This part is still a work in progress. At the point shown here, GPT2 had been trained on its own and the diffusion-on-rollout path had barely started, so the result is more of a proof-of-direction than a finished system.
I had planned to continue training this stage further, but even in this partial form it was enough to clarify the design tradeoffs.
In hindsight, I made several assumptions while still learning how I wanted to think about video modeling. If I revisited the project now, I would make a cleaner architectural choice: either stay more fully discrete and push the token-modeling side harder, or stay more fully continuous and use a stronger latent video model. This hybrid worked well enough to be informative, but it also made the interface between the discrete and continuous parts more awkward than it needed to be.
That is probably the real value of the project. It was not a polished final answer, but it was a useful experiment in modular video modeling. It taught me that even a somewhat clumsy decomposition can work if each part carries enough of the right structure, and it made me much more deliberate later about how to separate representation, rollout, and recovery.